OPINION -- Picture a program manager at the Pentagon with money to spend and a job to do: buy an AI tool that helps analysts summarize intelligence reporting. She has read the Defense Department's five ethical principles for AI. Systems must be responsible, equitable, traceable, reliable and governable. She agrees with every word. Then she opens a blank requirements document, and the principles are no longer enough. She needs specifics, benchmarks, evidence.
What accuracy counts as "reliable," measured on what? What does "traceable" require her to log, and for how long? When the vendor ships a new model version, is that a patch or a material change that sends the whole system back through testing? Should analysts see the model's confidence scores, and are those scores good enough that showing them helps rather than hurts? Who signs the deployment memo, and on what evidence?
Nothing in the policy corpus answers her. No consensus answer to these questions even exists. So she improvises, the way program offices always do when guidance runs out. Either she piles on every test she can imagine and fields the capability two years late, or she takes the vendor's benchmark numbers on faith and fields something nobody independently checked.
Speaking from years of experience inside the Pentagon trying to get software to the people who needed it, the vision was never the hard part. The desk was. Project DAEDALUS, a new effort from our lab at Vanderbilt, exists to fix the desk.
That desk is the subject of a new whitepaper from our lab at Vanderbilt, and the project that follows from it Data-, Acquisitions, and Expert-Driven AI Logistics for the United States (DAEDALUS). The short version: the United States has said what responsible AI in national security should look like and has not specified how to build it. The gap is not intent. It is specificity and evidence. And we are looking for your partnership—and your problems—to make it a success.
Start with a mistake nearly every framework makes: treating "AI" as one technology. The systems actually running in military, intelligence and cyber operations fail in different ways, at different speeds, with different amounts of warning.
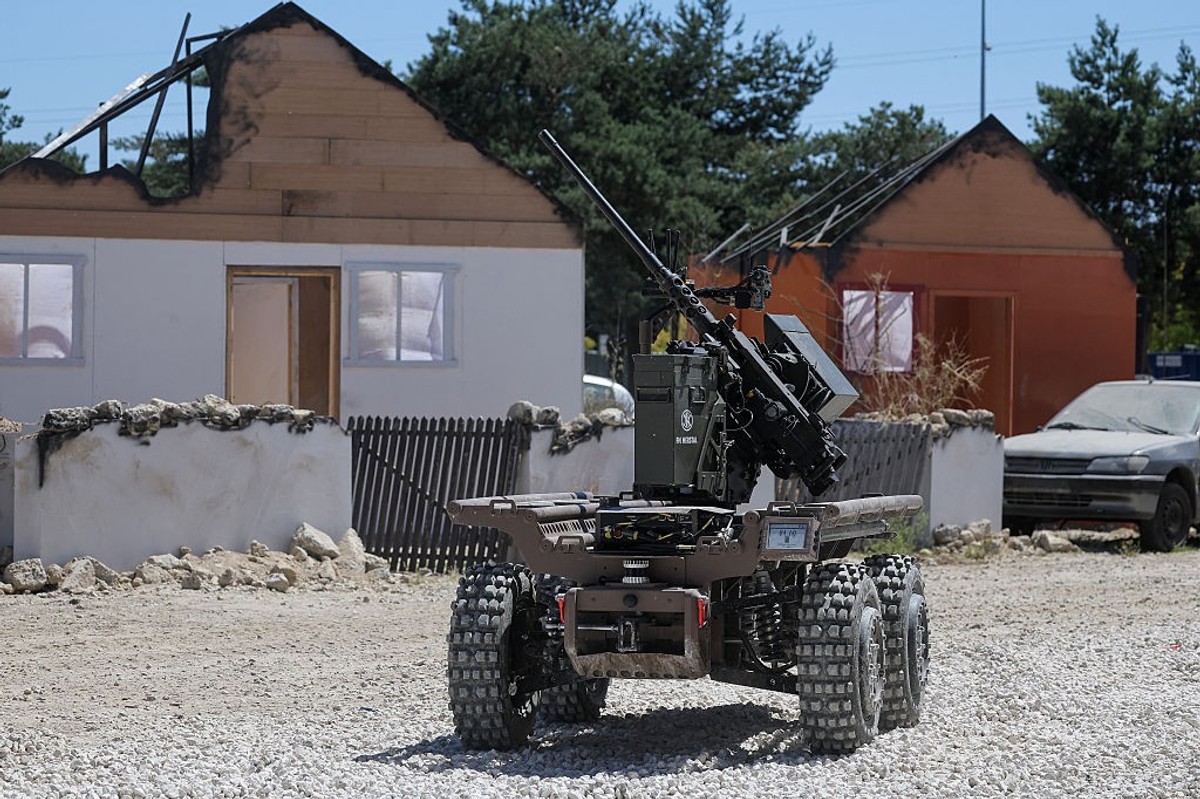
A classifier flagging objects in drone video advises a human who sees every output and catches most errors in seconds. A recommendation engine ranking targets or allocating logistics never acts either, but it sets the menu; an option it leaves off is gone no matter who holds the veto. A language model summarizing reporting produces fluent, confident prose that is wrong in ways you cannot see without going back to the sources. An agentic system defending a network takes action on its own, faster than anyone can review it; by the time an operator reads the log, the thing has happened. And a generative system making synthetic content raises a question the other four never do: not whether the output is right, but who authorized it, where it went and whether anyone can prove a machine made it.
One rulebook aimed at the middle of that range fails at both ends. Agentic-grade oversight on the classifier delays a low-risk tool for no reduction in risk. Classifier-grade "review the output" on the agent reviews an action that already occurred. Directive 3000.09 gets this right for autonomous weapons and says nothing about the other four. The one instruction that reaches generative AI covers public affairs only and says so. The test and evaluation manual excludes generative AI by its own terms. The capabilities driving near-term adoption are exactly the ones the rules skip.
The deeper problem is one almost nobody says out loud. Our AI governance is assertion-based, not evidence-based.
Every framework says systems should be tested. None reports what testing reveals: what accuracy a frontier model actually achieves on an intelligence task, how often it asserts things its sources don't support, whether its stated confidence tracks its real correctness. Every framework also says humans should exercise meaningful judgment, but they don’t specify where human review measurably improves outcomes, how often a reviewer under real time pressure catches a model's mistake, or how fast automation bias sets in once the system looks reliable. "Human in the loop" is a reassurance, not a specification; the Department's own Responsible AI pathway concedes it has no way to measure user trust. Finally, every framework says to monitor for drift—yet not one gives a drift rate or a monitoring cadence, and DoD's own cybersecurity tailoring guide admits those thresholds still have to be set.
A recommendation without a number cannot be argued with, refined or falsified. It cannot be prioritized either. When nobody has measured which safeguards catch which failures at what cost, every safeguard looks equally warranted, so the cheap ones get done and the rest get waived. It is a building code that demands "adequate" fire protection without anyone ever having set a building on fire. Much of the missing data exists. It sits in classified test records, vendor files and program folders that were never meant to be published. The open literature has almost none of it.
Then there is the clock. Directive 3000.09 was issued in 2012 and reissued in 2023. In between, the transformer was invented, scaled and productized; large language models went from curiosity to daily tool; reasoning models and agents arrived. The NSCAI final report, still our most complete strategic treatment, was published before ChatGPT existed. Executive Order 14110, which carried real substance on dual-use model evaluation and red-teaming, was revoked days into the new administration, and its content left with its branding. Policy revises in years. Capability moves in months. A document with no update mechanism is not at risk of going stale. It is guaranteed to.
This is not to say we should have fewer guardrails. Our lab has argued we should test frontier AI like a weapon, and we still believe it. But every framework treats deployment as the risky act and non-deployment as the safe default, and in a competition with China that is incomplete. Beijing's military writing puts AI-enabled operations at the center of future war with no comparable public ethics regime. Russia has fielded AI-enabled targeting in Ukraine, with limited success and real learning. Not fielding a capability that would improve detection, decision speed or defensive coverage carries risk too, and no one has tried to size it.
The question is not whether to constrain. It is which constraints buy real risk reduction and which impose cost for nothing, and you cannot answer that without measuring what each safeguard actually catches. Specific, evidence-based guidance does not slow fielding. It speeds it, by removing the uncertainty that makes program offices over-test or surrender.
So the Wicked Problems Lab at Vanderbilt's Institute of National Security is writing a field guide: an evidence-based manual based on what actually works in the field, right now, and continues to evolve over time as the technology and evidence progresses. It’s not another set of principles; but a translation layer one level below them. It takes the five DoD principles as given and sorts systems into the five categories above. For each, it answers the same six questions: who approves deployment and what cannot be delegated; what tests and thresholds establish readiness; how work and authority split between operator and machine; what counts as a material change requiring revalidation; how the system fails, how fast it halts and what rollback looks like; and how an adversary attacks it and what risk remains after the defenses. Every recommendation carries a tag. Measured means we or a partner published the data. Inferred means the evidence comes from an adjacent field and probably transfers. Open means it is a judgment, and we say so.
Version 1.0 will have more Open tags than Measured ones. We are publishing it anyway, in January 2027, with one original data release: measured veracity and unsupported-assertion rates for current frontier models on analytic tasks, protocol included. Hiding the extent of what is unknown would recreate the deficit we are trying to close. Then we revise every three months, with a changelog that records which recommendations changed because new evidence contradicted the old. Everything is unclassified and reproducible, and we are not taking money from the organizations whose data we publish.
We believe that partnerships will help solve problems with AI implementation. If your program office, test agency, FFRDC or company holds evaluation results, drift measurements or testing cost and timeline figures releasable in anonymized form, we want them, on your terms of attribution, with your review before anything is published. We also need module authors with depth in one capability area, and reviewers willing to give us one cycle a quarter. If you are interested in Project DAEDALUS, our contact address is wpl@vanderbilt.edu.
We have said what good looks like. Now, it's time to show our work—together.
Brett J. Goldstein is a Research Professor and Special Advisor to the Chancellor on National Security at Vanderbilt University, where he directs the Wicked Problems Lab at the Institute of National Security. He previously led the Defense Digital Service at the Pentagon.
Ian Miller is a Research Engineer at the Wicked Problems Lab in the Institute of National Security at Vanderbilt University. He holds a PhD in AI from Vanderbilt University, with publications on detecting AI-generated content and defending against data poisoning.
The Cipher Brief is committed to publishing a range of perspectives on national security issues submitted by deeply experienced national security professionals. Opinions expressed are those of the author and do not represent the views or opinions of The Cipher Brief.
Have a perspective to share based on your experience in the national security field? Send it to Editor@thecipherbrief.com for publication consideration.
Read more expert-driven national security insights, perspective and analysis in The Cipher Brief